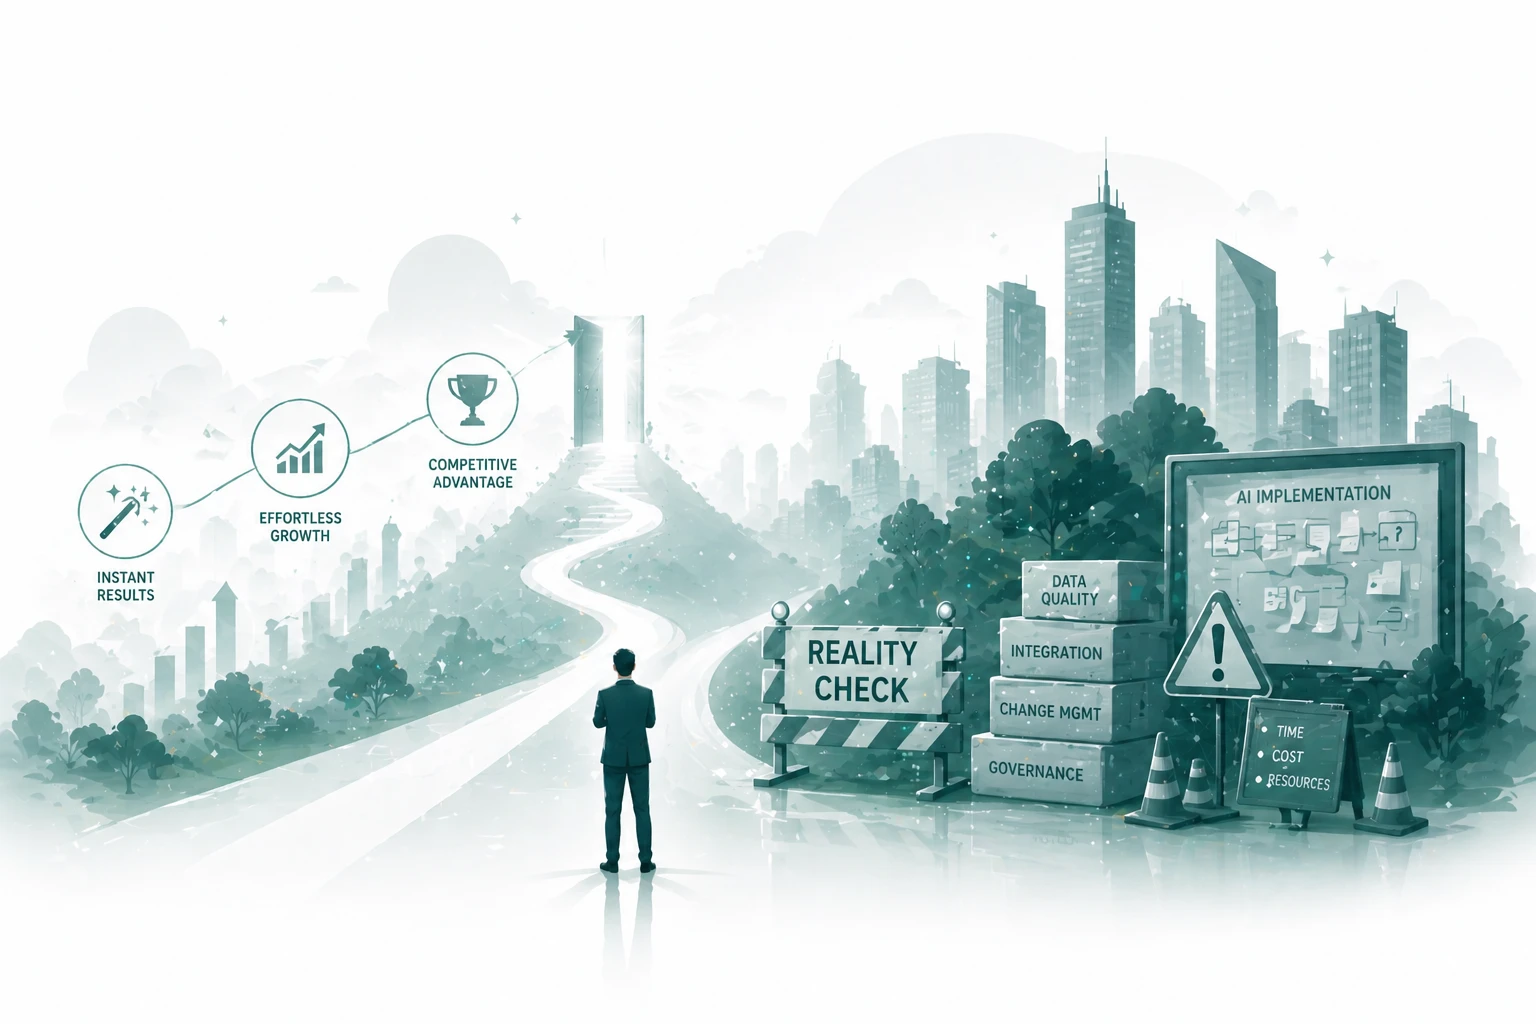
Reality Check: AI Isn't Magic (Yet)
August 2025 produced three reality checks in close succession: MIT's NANDA project found roughly 95 percent of enterprise GenAI pilots return zero P&L impact, OpenAI's long-awaited GPT-5 landed as iteration rather than leap, and Apple's reasoning-model paper documented hard limits where today's models actually break. The era of treating AI as magic is closing, the era of treating it as real engineering is starting.
August 2025 produced three reality checks in close succession. MIT's NANDA project published "The GenAI Divide: State of AI in Business 2025", finding that roughly 95 percent of enterprise generative-AI pilots produce no measurable P&L impact. OpenAI shipped GPT-5 to a reception so mixed that the company restored GPT-4o within a week. And Apple's reasoning-model paper kept circulating, documenting hard complexity ceilings where today's reasoning models simply collapse. None of this means AI isn't useful. It means the era of treating it as magic is closing, and the era of treating it as real engineering is starting.
For three years the enterprise narrative was that AI capability was on an exponential curve and adopting it was the only relevant question. By late August 2025 the data has changed the conversation. Capability gains are still real, but the gap between what gets demoed and what survives in production has become measurable, repeatable, and, in three specific places, impossible to argue with.
The 95 percent finding
In mid-August, MIT's Project NANDA released "The GenAI Divide: State of AI in Business 2025". The headline number is the one that ended up in every board deck: of the more than 300 enterprise generative-AI pilots reviewed across 2024 and the first half of 2025, roughly 95 percent showed no measurable impact on profit and loss. The researchers framed it as a "GenAI Divide", a small group of companies extracting real value, and a much larger group running pilots that never make it past pilot.
The reasons named in the report were not surprising. Most pilots had no clearly defined baseline, no measurement framework agreed before the work started, no integration with the data and workflows that actually drive the business, and no governance posture strong enough to put the model anywhere near sensitive material. Pilot success in a sandbox does not translate into P&L impact when the model can't reach the data that matters.
The number that should worry every CIO is not 95. It is the implicit corollary: the 5 percent who succeeded did not have better models. They had better measurement, better integration, and better governance.
GPT-5: iteration, not leap
On 7 August 2025 OpenAI released GPT-5. The launch was framed as the next discontinuous jump, the company's most ambitious release to date and a public answer to the question of whether the scaling laws still hold. The reception did not match the framing.
Within a week, two things were clear. First, the underlying capability gains were real but incremental rather than revolutionary, better at coding, better at multi-step reasoning, modestly better on most evals, but a long way from the qualitative jump from GPT-3.5 to GPT-4. Second, the rollout itself was rough: a model-routing layer made GPT-5 feel inconsistent on day one, and the deprecation of GPT-4o produced a user revolt strong enough that OpenAI brought GPT-4o back within days. Sam Altman acknowledged the misstep publicly.
The lesson isn't that GPT-5 failed, it is genuinely the most capable model OpenAI has shipped. The lesson is that the most-anticipated AI launch of 2025 turned out to be an iteration, not a leap. Enterprises that built strategy around the assumption of continuous discontinuous breakthroughs need to plan for a curve that bends more than it jumps.
Where reasoning models actually break
The third reality check is older but matured during the summer. Apple's June paper "The Illusion of Thinking", by Parshin Shojaee, Iman Mirzadeh, and colleagues, used controlled puzzle environments (Tower of Hanoi, river-crossing variants, blocks-world tasks) to test the latest reasoning models, including DeepSeek-R1 and Claude 3.7 Sonnet's extended thinking mode. They identified three regimes: at low complexity standard models actually outperform reasoning models; at moderate complexity reasoning helps; at high complexity both regimes collapse to near-zero accuracy, with reasoning models often using fewer thinking tokens just before they fail.
The paper drew rebuttals through the summer, including a piece sharply titled "The Illusion of the Illusion of Thinking", but the central finding has held up: today's reasoning models are not doing fully general reasoning. They are doing pattern-matched search over distributions they have seen. That distinction matters in production. Where the work distribution is well-covered by training data and the chains of reasoning are short, these models are spectacular. Where it isn't, they fail in confident-sounding ways.
For an enterprise, that means the question is no longer "is the model smart enough?" but "is this task inside the distribution where the model is reliable, and how do we know when it isn't?"
What this means for European enterprises
For organisations in Switzerland, Germany, and the broader EU, August 2025 has three operational implications.
Temper executive expectations against the data. The 95 percent figure is not an attack on AI. It is the maturity curve every transformative technology goes through. Cloud, mobile, even ERP all had years where the marketing outpaced the realised value. The right response is not less ambition, it is more honest measurement and a willingness to kill pilots that aren't moving a number.
Build for hybrid intelligence, not autonomy. The Klarna reversal in May, the GPT-5 rollout in August, and the Apple paper all point in the same direction: today's models are powerful collaborators, not autonomous workers. The architecture that survives is human-in-the-loop with clear escalation, not fire-and-forget agents on critical workflows.
Governance is now a value lever, not a tax. The 5 percent of organisations that extracted P&L value did so by giving their models access to the data and workflows that mattered. They could only do that because they had a governance posture, data-loss prevention, role-aware access, audit trails, retention controls, strong enough to make that access defensible. In regulated industries the order of operations is governance first, then value. There is no other order that survives an audit.
The "yet"
The honest framing of August 2025 is not "AI doesn't work". It is "AI isn't magic, and it never was". The systems are extraordinary, the productivity gains in narrow tasks are real, and the trajectory remains upward. What's changed is that the field has earned enough scars to know what doesn't work, naive autonomy on critical workflows, pilots without measurement, capability claims without governance, and the assumption that the next model will solve last quarter's integration problems.
For European enterprises, that reality check is opportunity, not threat. The companies that win the next two years are the ones already operating as if the magic never existed, measuring outcomes, governing access, and letting AI earn its budget the same way every other piece of enterprise infrastructure had to.